Make it real,
then make it better.

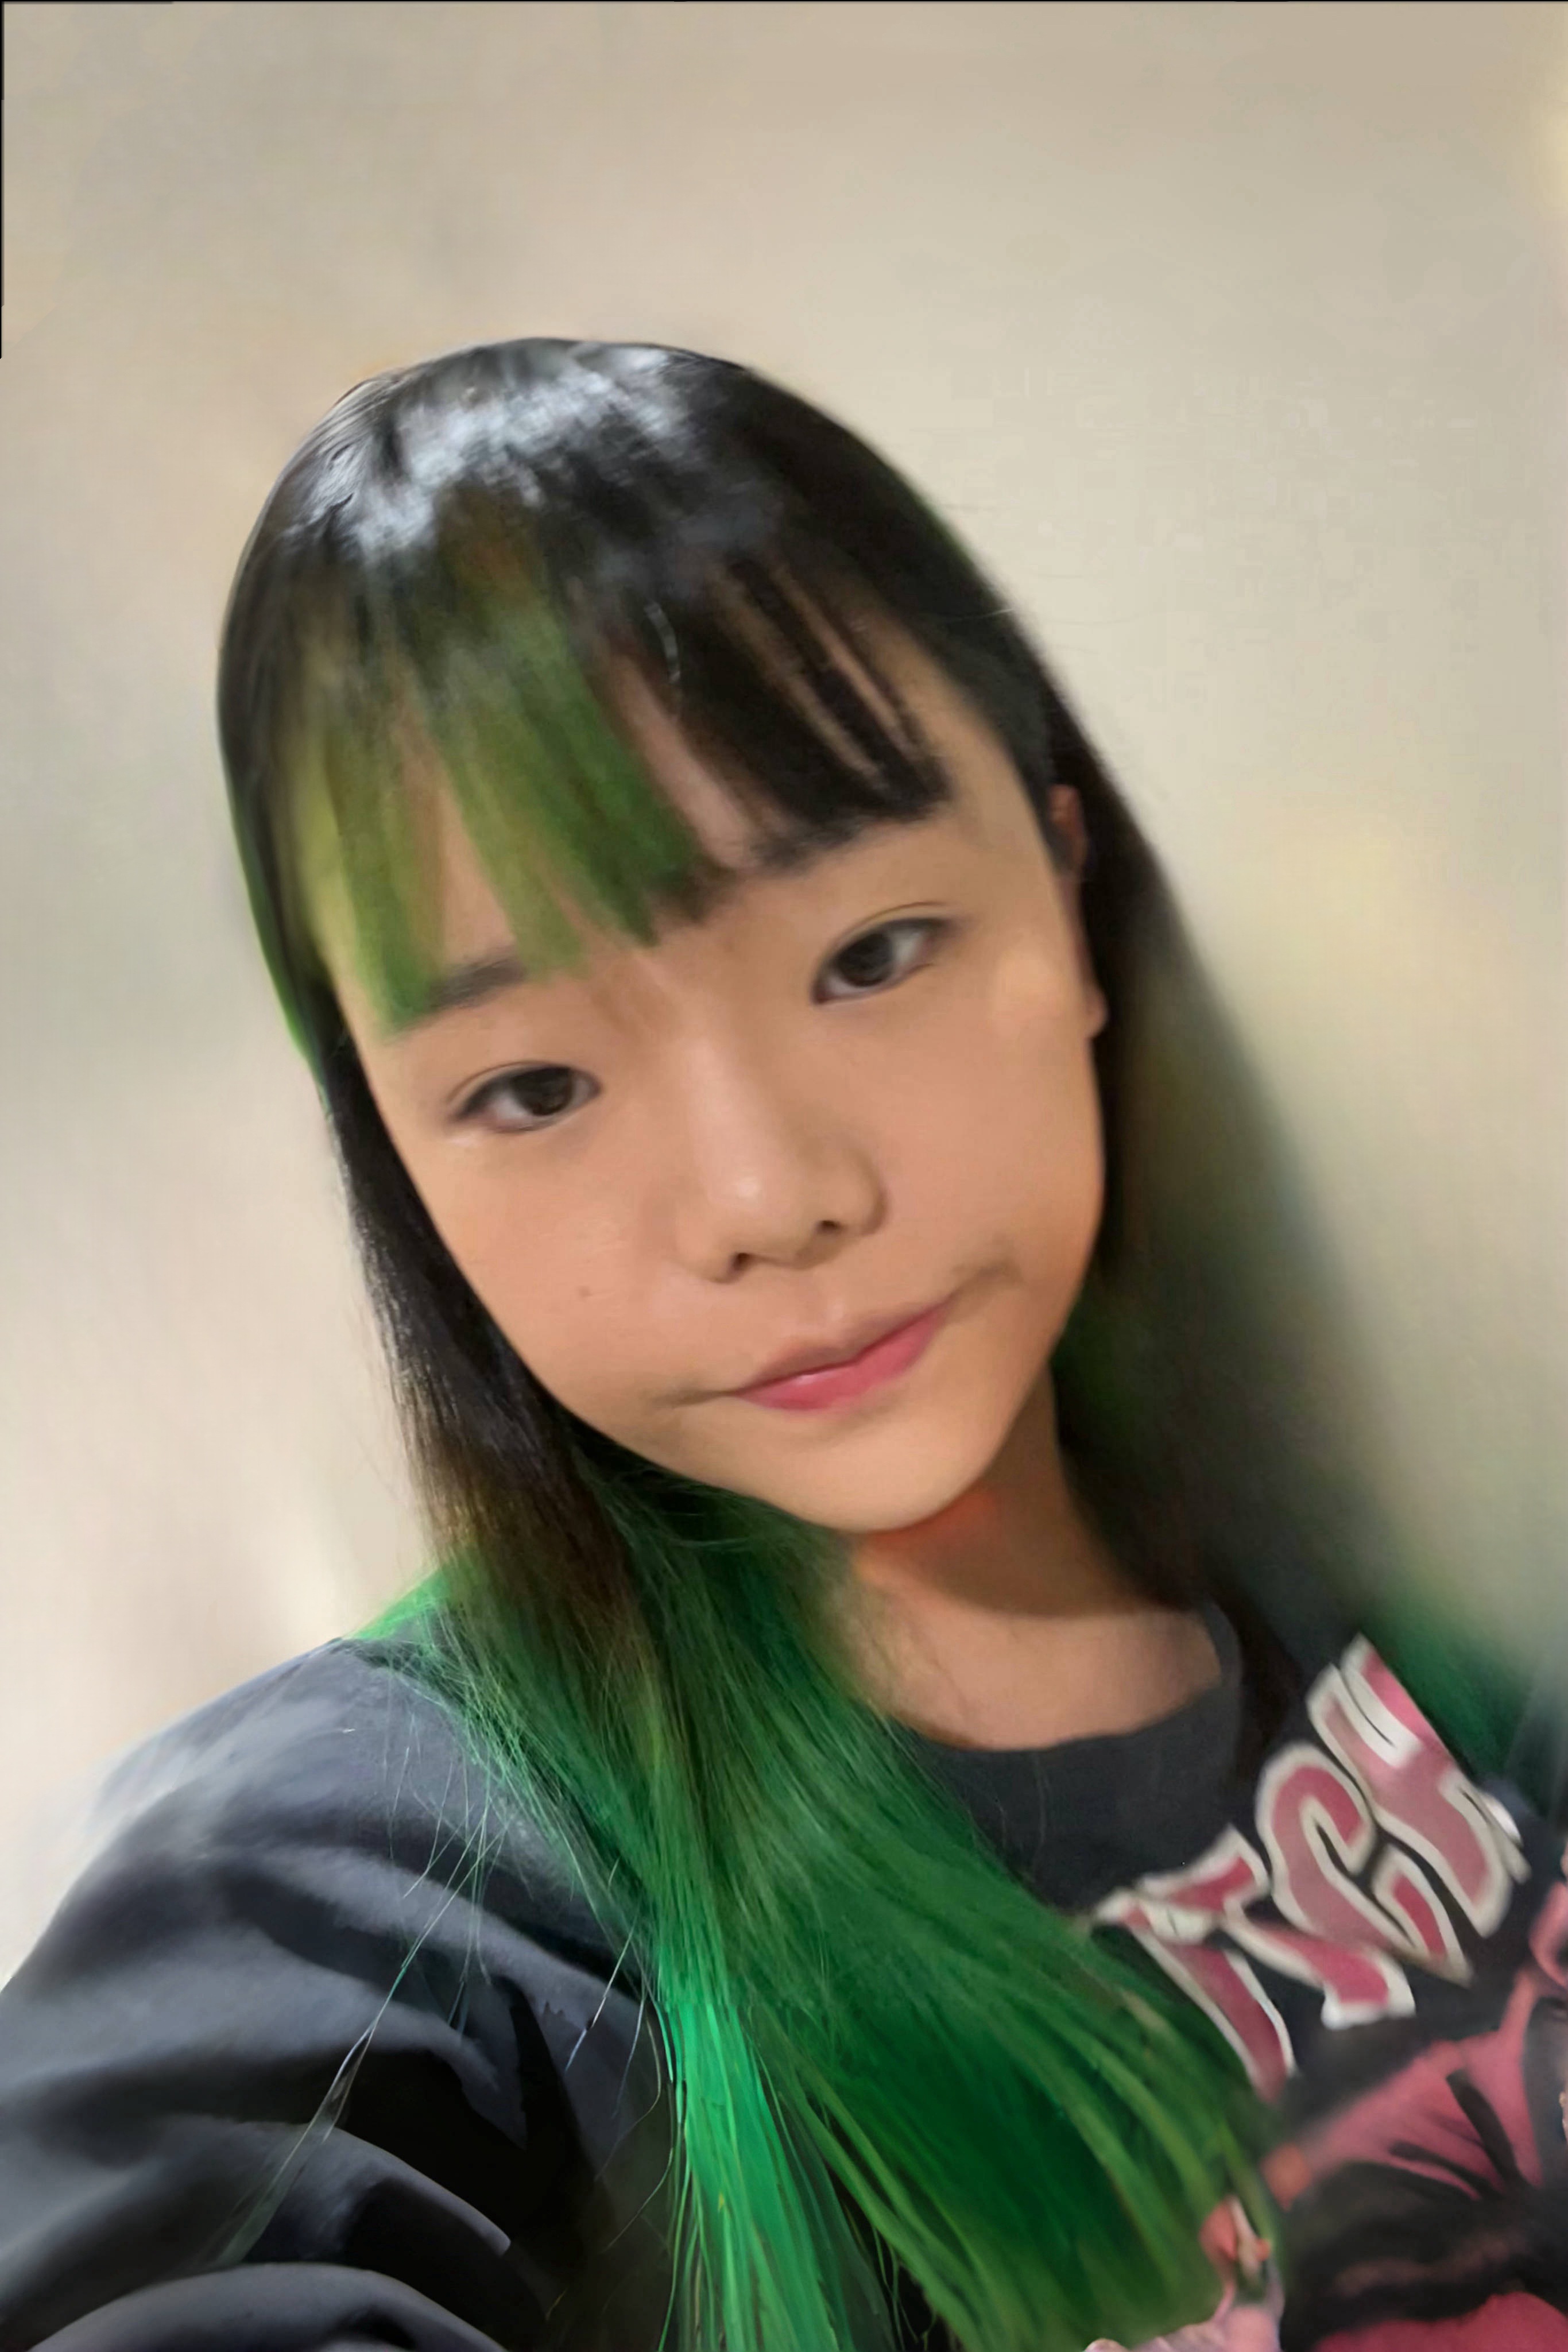
Yunong Liu

Research @ Luma AI

My research at Luma AI spans multimodal image and video generation, world models, and structured visual generation, with a focus on post-training, reward modeling, and evaluation.

My current interest is moving visual generative models beyond flat pixels: toward structured, editable, and verifiable representations that can support reasoning, simulation, and eventually action in physical or interactive environments.

I led research and system development for Layering, a structured visual generation system that transforms generated images and design media into editable raster, text, and vector layers, enabling multi-turn editing by people and agents.

My work also spans Luma's Ray3 and Uni-1 models. For Ray3, I built the experimental post-training workflow connecting video generation, reward modeling, VLM-as-judge graders, and held-out evaluation, and explored diffusion RL, DPO-style, and GRPO-style approaches. For Uni-1, I contributed to reinforcement learning, data, and evaluation experiments, including OCR-focused rewards, caption and data ablations, and early evaluation.

Before Luma, I completed my MS in Computer Science at Stanford with Jiajun Wu, where my research focused on visual understanding, spatiotemporal grounding, and multimodal evaluation. I hold a BEng in Electronics and Computer Science from the University of Edinburgh.
Yunong Liu Yunong Liu AI 1 Yunong Liu AI 2 Yunong Liu AI 3 Yunong Liu AI 4 Yunong Liu AI 5

Selected Work

Layering

July 2026

Layering turns a flat generated image into editable raster, text, and vector layers, structured enough for people and agents to inspect, revise, verify, and rebuild across multiple turns.

  • Led research and system development for Layering, from structured visual generation to multi-turn editing and evaluation.

Hover the preview to peel it apart · hover a layer to name it · ‹ › to switch design

Uni-1

March 2026

Uni-1 is Luma's unified multimodal model for interleaved language and image understanding, reasoning, and generation.

  • Contributed to reinforcement learning, data, and evaluation experiments for Uni-1, with a focus on OCR rewards and the effects of caption and training data choices.

Ray3

September 2025

Ray3 is Luma's video generation model, supporting controllable video-to-video generation, character references, keyframes, and HDR.

  • Built Ray3's experimental post-training workflow, integrating video sampling, reward modeling, and held-out evaluation to study reinforcement learning for video generation.

This Year ✨

This year, I am interested in visual generation as a bridge between pixels, structure, code, feedback, and action. I want generated artifacts to be more than flat outputs: structured states that people and agents can inspect, revise, verify, and reuse in interactive multi-turn workflows.

In design, this means layouts, diagrams, interfaces, product visuals, SVG, HTML, UI components, and other code-backed representations. In coding, it means artifacts that agents can read, modify, test, and verify instead of treating visual outputs as opaque images. In video and embodied settings, it points toward visual models that preserve spatial, temporal, and object-level structure well enough to support downstream reasoning and action.

Layering was one attempt at this direction, with reward design and repeated-edit evals as the feedback loop around it. I build evaluations that measure instruction following, language grounding, information preservation, edit success over repeated interventions, and usefulness in real workflows. These evaluations guide data, reward, conditioning, and model changes.

Selected Publications

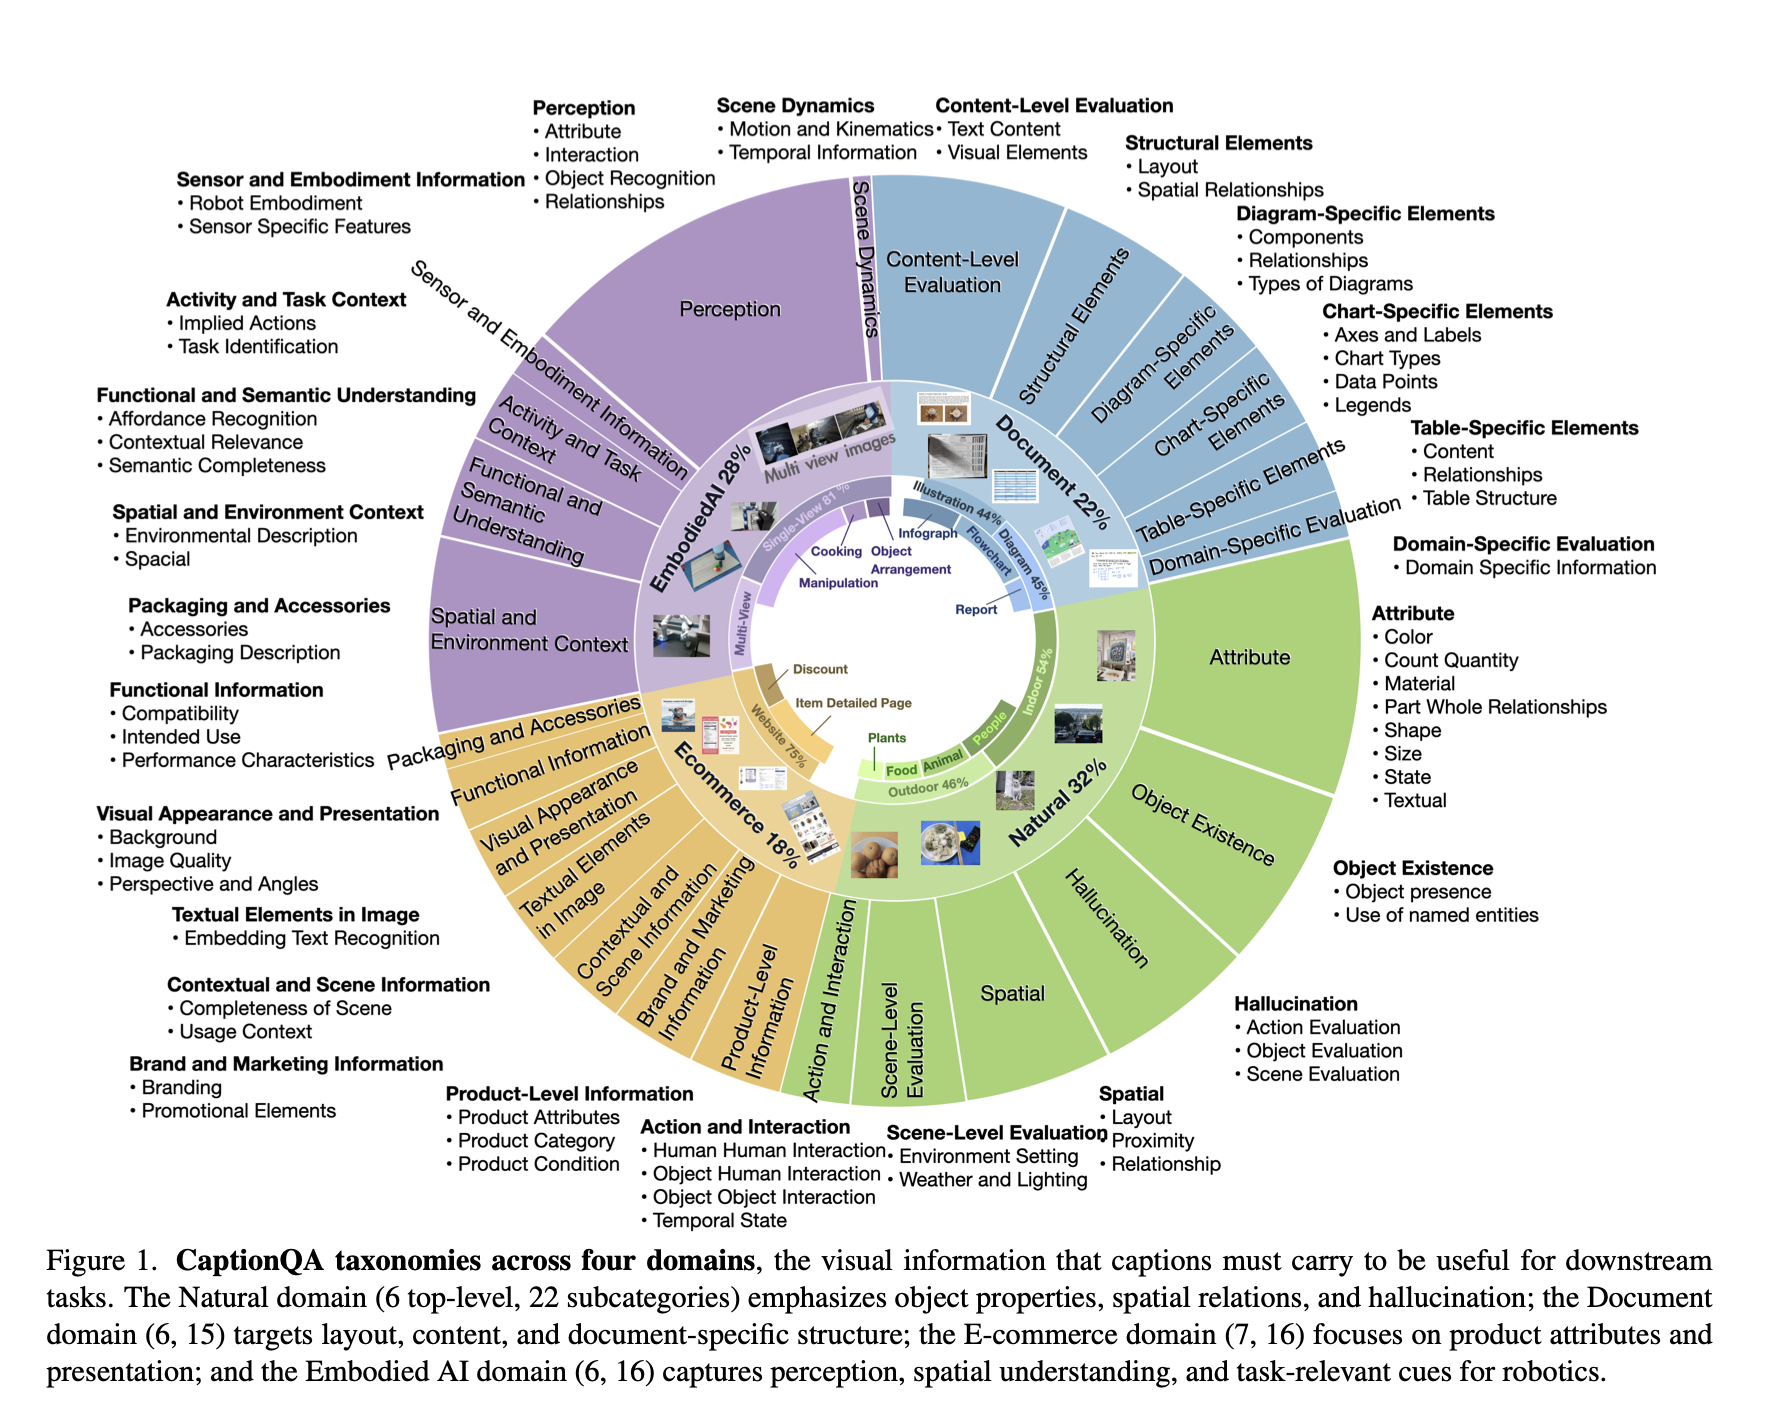
CaptionQA Taxonomy

CaptionQA: Is Your Caption as Useful as the Image Itself?

Shijia Yang*, Yunong Liu*, Bohan Zhai*, Ximeng Sun, Zicheng Liu, Emad Barsoum, Manling Li, Chenfeng Xu.

(*equal contribution)
CVPR 2026 / Paper / GitHub /

Introduces CaptionQA, a utility-based benchmark with 33,027 multiple-choice questions across Natural, Document, E-commerce, and Embodied AI domains. It measures how well captions preserve the information needed for downstream tasks, revealing gaps between image and caption utility even for state-of-the-art multimodal models.

Taming generative video models for zero-shot optical flow extraction

Seungwoo Kim*, Khai Loong Aw*, Klemen Kotar*, Cristobal Eyzaguirre, Wanhee Lee, Yunong Liu, Jared Watrous, Stefan Stojanov, Juan Carlos Niebles, Jiajun Wu, Daniel L. K. Yamins.

NeurIPS 2025 / Paper / Code / Project Page /

Introduces a counterfactual probe over video-diffusion logits that extracts optical flow with no labels and no fine-tuning. The method achieves state-of-the-art TAP-Vid results, generalizes to in-the-wild videos, and outperforms specialized optical-flow baselines.

IKEA Manuals at Work

IKEA Manuals at Work: 4D Grounding of Assembly Instructions on Internet Videos

Yunong Liu, Cristobal Eyzaguirre, Manling Li, Shubh Khanna, Juan Carlos Niebles, Vineeth Ravi, Saumitra Mishra, Weiyu Liu*, Jiajun Wu*.

NeurIPS Datasets and Benchmarks Track 2024 / Paper / Project Page / X (Twitter) Thread /

Introduces a dataset and grounding framework that align real-world assembly videos with 3D models and instruction manuals, tracking assembly structure over time. Cross-frame optimization with temporal-consistency constraints supports 4D grounding across 34k+ frames from 98 videos.

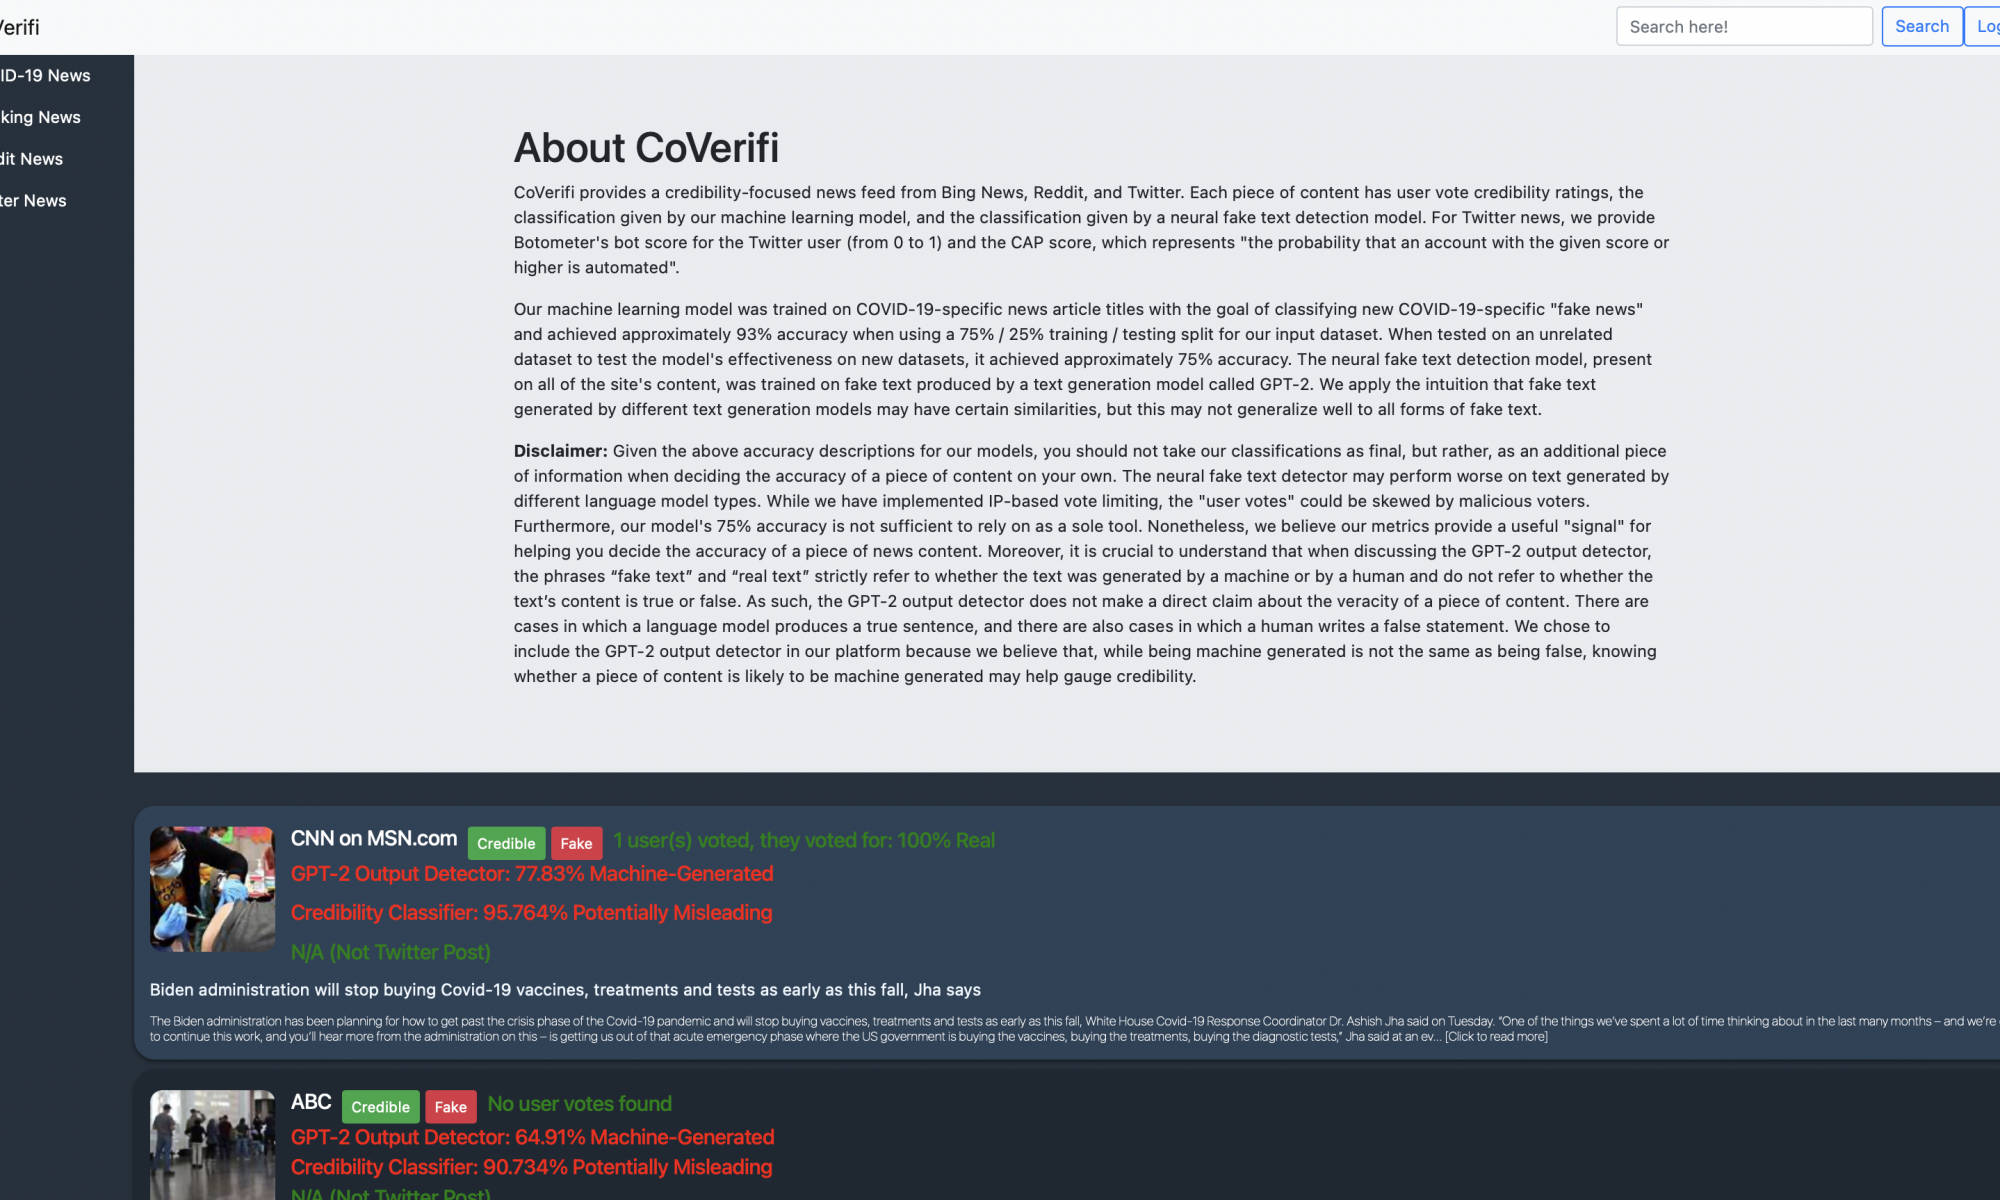
COVID-19 Misinformation Detection

COVID-19 Misinformation Detection: Machine-Learned Solutions to the Infodemic

Yunong Liu*, Nikhil Kolluri*, Dhiraj Murthy.

(*equal contribution)
JMIR Infodemiology Vol 2, No 2 (2022) / Paper

Developed hybrid framework combining machine learning with crowdsourced annotations to combat COVID-19 misinformation. Developed systematic comparison framework across classical models (SVM, LR, BNB) and pre-trained models (BERT, RoBERTa, XLNet) on 7 dataset combinations.

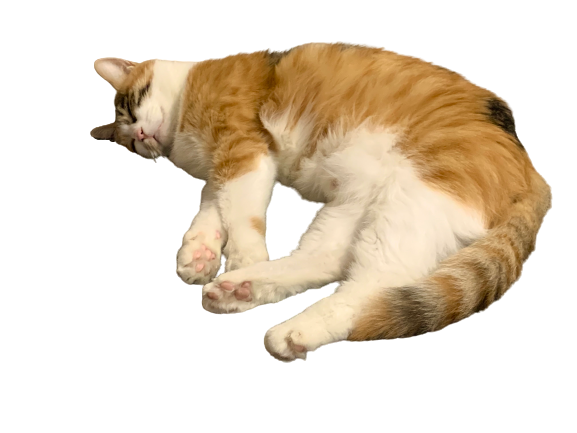
My Purr-fect Companions

Mewomewo

Mewomewo

DoB: October 1, 2012

Role: The Elegant Lady

Superpowers: Tsundere Queen Cleanliness Lover Fearless Explorer

Mewomewo is the queen of the house since 2012. She acts cool but secretly loves attention. She's super brave, except when it comes to mess. You'll often see her checking if the house is clean and tidy.

Xiaopang

Xiaopang (Little Fat)

DoB: July 17, 2014

Role: The Cuddly Foodie

Superpowers: Cuddle Expert Food Lover Master of Stealth (when scared)

Xiaopang, our big bundle of love, joined us in 2014. His name means "little fat", but really, he's just extra cuddly! He loves snuggles and treats equally. He might get scared easily, but his heart is as big as his appetite.